Design a URL Shortener (TinyURL / bit.ly) — System Design
The classic system design warm-up, solved end to end: requirements, scale estimation, Base62 short codes, generating unique codes without collisions, the data model, caching the redirects, and scaling.
🟠 High-Level Design · Senior interview favourite · the classic warm-up
"Design a URL shortener like TinyURL or bit.ly." It's the most common opening system-design question there is — simple enough to finish in 45 minutes, deep enough to reveal how you think. If you can walk this one cleanly, you've shown the whole method: clarify requirements, estimate scale, design the API and data, pick the core algorithm, and scale the reads. Let's do it end to end, the way you would on a whiteboard.
code → long URL in a database, and on each visit look up the code and redirect. The interesting parts are how you generate unique codes and how you serve billions of redirects fast.
Step 1 — Clarify requirements
Always start here; never jump to a diagram. State the scope out loud:
- Functional: given a long URL, return a short one; visiting the short URL redirects to the original. Optionally: custom aliases, expiry, click analytics.
- Non-functional: highly available (a dead redirect breaks every shared link), low latency on redirect, and short codes that stay short. It's extremely read-heavy — links are created once and clicked many times.
Step 2 — Estimate scale
🟠 A quick back-of-the-envelope sizes the design. Assume 100M new URLs/day and reads 100× writes:
writes: 100M/day ÷ 100k s  ≈ 1,000 writes/sec
reads : 1,000 × 100         ≈ 100,000 reads/sec   ← the real challenge
storage: 100M × 500 B/day → ~18 TB/yr → ~90 TB over 5 yrs
Two facts fall out: 100K reads/sec means caching is mandatory, and 90 TB means the data won't fit on one machine, so we'll need to shard eventually.
Step 3 — How long is the short code?
🟠 The codes use Base62 (a–z, A–Z, 0–9 = 62 characters). How many characters do we need? Each character multiplies capacity by 62:
- 6 characters → 62⁶ ≈ 56 billion combinations.
- 7 characters → 62⁷ ≈ 3.5 trillion.
At 100M/day, 56 billion lasts over 1,500 years — so 7 characters is comfortably future-proof. Short, and effectively unlimited.
Step 4 — The core problem: generating unique codes
🔴 This is the heart of the interview. Three approaches, from naive to solid:
| Approach | Idea | Catch |
|---|---|---|
| Hash the URL | Take MD5/SHA of the URL, keep first 7 chars | Collisions — two URLs can map to the same code; you must check & retry |
| Counter + Base62 | Keep a global counter; encode the next integer in Base62 | No collisions ever, but the counter must be distributed/unique |
| Key Generation Service (KGS) | Pre-generate unique keys offline; servers grab a batch | One more component, but fast & collision-free |
🔴 The clean answer is counter + Base62. A monotonically increasing number is guaranteed unique, and encoding it in Base62 gives a short code — no collision checks needed. The only question is how to make the counter unique across many servers. Options: a single source with ranges handed out in blocks (each server claims IDs 1–1000, 1001–2000, …, so it doesn't call the counter on every request), or a distributed ID generator. Naming "counter in Base62, with ID ranges pre-allocated per server" is the senior-grade response.
Step 5 — API and data model
POST /shorten   { longUrl }          → { shortUrl }
GET  /{code}                         → 301 redirect to longUrl

TABLE urls:
  short_code   VARCHAR(7)  PRIMARY KEY   ← indexed for O(1) lookup
  long_url     TEXT
  created_at   TIMESTAMP
  expires_at   TIMESTAMP (nullable)
🟠 A subtle but classic detail: use a 301 (permanent) redirect to let browsers cache it and cut load, or a 302 (temporary) if you want every click to hit your server (so you can count analytics). Mentioning that trade-off scores points. The data is simple key–value, so a key-value store or an indexed SQL table both work.
Step 6 — Architecture (putting it together)
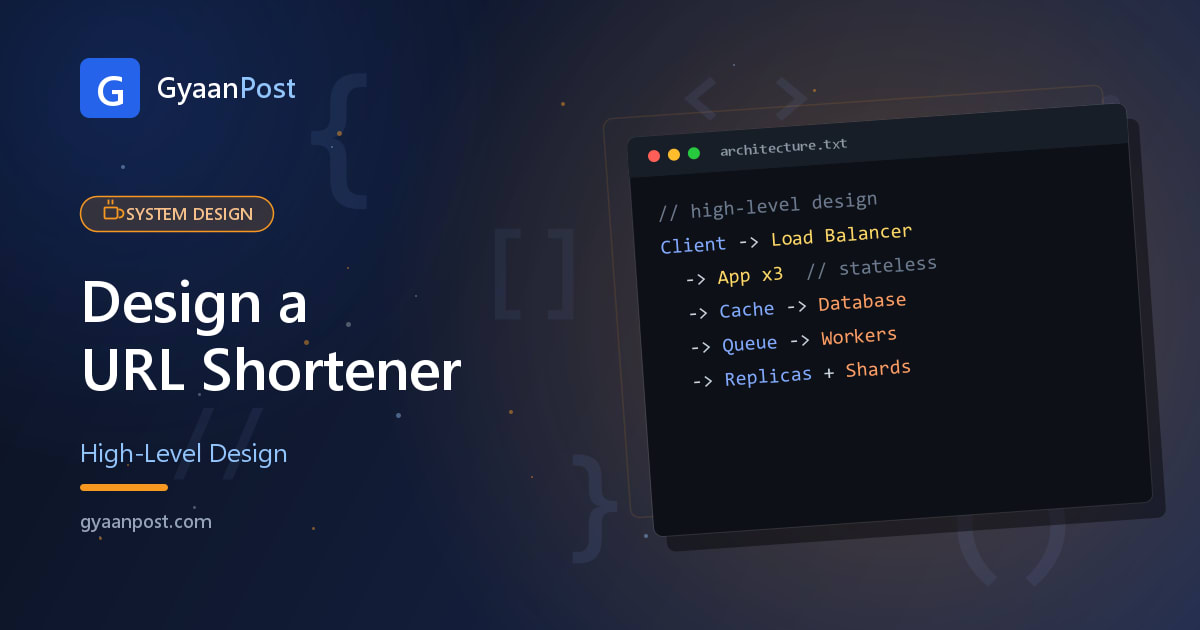
The redirect path is what we optimise: request → app server → check cache (Redis) → on hit, redirect immediately; on miss, read the DB, populate the cache, redirect. Because a small set of links get most clicks (the classic 80/20), the cache absorbs the vast majority of that 100K reads/sec, and the database is barely touched.
Step 7 — Scaling the pieces
- Reads: the cache does the heavy lifting; add read replicas behind it for misses.
- Storage: shard the DB by short_code so 90 TB spreads across machines.
- Availability: replicate everything and front it with a load balancer; a global service adds a CDN/edge layer so redirects resolve close to users.
The interview-ready walkthrough
"I'd confirm the requirements (create short link, redirect, read-heavy, high availability), estimate ~1K writes and ~100K reads/sec, and use a 7-char Base62 code. For uniqueness I'd use a counter encoded in Base62 with ID ranges pre-allocated per server — no collisions, no checks. Store code → URL in a sharded key-value store, and put the redirect path behind a Redis cache so the 100K reads/sec mostly never touch the DB. Add replicas, sharding, and a load balancer for scale and availability, and a CDN for a global audience." That hits every phase cleanly — which is exactly why this question is the perfect warm-up."
What to read next
- Design a Rate Limiter — the next classic HLD problem
- Caching Strategies — the cache that carries the read load here
- Database Sharding — how the 90 TB is split
- ← The complete System Design guide (hub)
← How to approach a design interview · Design a rate limiter →